Support Triage Lab
Synthetic benchmark Synthetic data: Ledgerly
Suggested routing for support tickets that improves on noisy manual categories and sends anything uncertain to a person, evaluated on accounts and months the model never saw.
- Status
- Code on GitHub
- Relevant to
- Data and analytics, AI and agents
Results · Synthetic data: Ledgerly
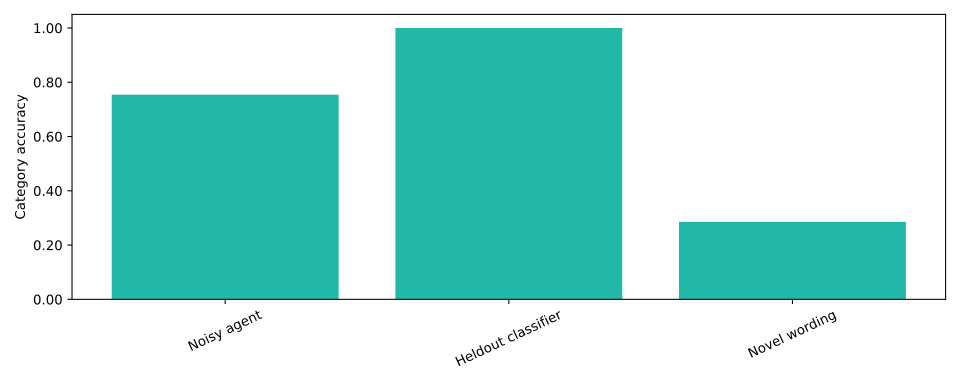
- Synthetic benchmarkSynthetic data: Ledgerly. Measured against a hidden answer key in that data. It shows the method works there, not a production result.category accuracy on the synthetic test set, against 75.4% for the noisy agent labelsSynthetic benchmark
- Synthetic benchmarkSynthetic data: Ledgerly. Measured against a hidden answer key in that data. It shows the method works there, not a production result.accuracy on separately written novel tickets, every one of which is sent to human reviewSynthetic benchmark
At a glance
- Question
- Can suggested routing beat noisy manual ticket categories, and know when to hand off to a person?
- Data
- Ledgerly’s synthetic support tickets, plus fourteen novel tickets written separately and never used for training.
- Compared with
- The agents’ own, noisy categories.
- How it was tested
- Train, validate and test on different accounts and later months, with the review threshold chosen on validation only.
- Result
- 100% category accuracy on the synthetic test set against 75.4% for the agent labels, but 28.6% on the novel tickets, every one of which goes to review.
- What it doesn’t show
- Synthetic templates inflate the test score. The novel-ticket result is the more realistic signal.
The problem
Agent-assigned ticket categories are noisy, so a model trained on them can look accurate while learning the noise. A routing model also has to know when not to route.
What I built, in detail
- A TF-IDF and logistic regression baseline trained on noisy agent categories, with a confidence threshold chosen on a separate validation set.
- Account-separated, time-ordered splits: training, validation and test use different accounts and later months.
- A novel-wording stress test written separately from the data generator, never used for training or threshold selection.
- A standalone HTML report, machine-readable metrics and CSV evidence, regenerated in CI.
How I checked it
- The novel-wording result is reported as evidence against trusting the synthetic score, not hidden.
Limitations
- A local ML baseline, not an LLM or an agent. Synthetic templates inflate results even across accounts and time.
Stack
Python, scikit-learn, pandas, pytest, GitHub Actions